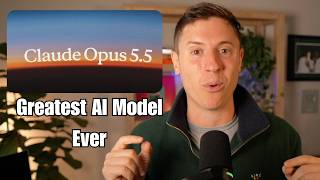
Claude Opus 5.5 is the greatest AI model ever released
Alex Finn · 2026-09-23 · review · 56,114 views
What's in the video
Description written by Gemini, which watched and listened to the whole video.
Summary
In this video, a tech creator presents a hands-on review and demonstration of Anthropic's Claude Opus 5.5, which he received early access to evaluate. He highlights its coding capabilities, reduced API pricing, improved speed, and more natural conversational tone compared to predecessor models and competing systems like OpenAI's GPT-6 Astra.
What is shown
- [00:00] Overview slides declaring Claude Opus 5.5 the "Greatest AI model ever", comparing it to Fable 5.1 and GPT-6 Astra.
- [01:40] An API pricing comparison table displaying per-million token costs for Claude Opus 5.5 versus Claude Opus 5.
- [02:14] A benchmark plot of "Agentic terminal coding by effort level" on Terminal-Bench 4.0 comparing Opus 5.5, Opus 5, Fable 5.1, GPT-6 Astra, and GPT-5.6 Sol.
- [02:56] A showcase of HubSpot for Startups' "5 Claude Skills" pack for founder-led marketing workflows.
- [05:34] A terminal session (
opuscoder) showing Claude running build checks, automated tests, and summarizing game engine bugfixes in clean markdown tables and bullet points. - [07:19] A gameplay demo of "CCGAME", a top-down 3D extraction shooter built using Claude Opus 5.5, featuring an inventory screen, map navigation, combat, looting, and extraction mechanics.
- [08:27] A chat log where Opus 5.5 brainstorms and develops an Apple Watch integration allowing the creator to monitor agent activities and message AI agents from his watch.
Claims & numbers
- The presenter claims Claude Opus 5.5 is smarter and significantly faster than Claude Fable 5.1 and GPT-6 Astra.
- According to the pricing table shown [01:41], Claude Opus 5.5 pricing per 1M tokens is $4 for input tokens (down from $5 on Opus 5), $20 for output tokens (down from $25), $0.20 for cache reads (down from $0.50), and $5 for cache writes (down from $6.25).
- On the Terminal-Bench 4.0 agentic coding benchmark [02:14], the presenter states that the "high" setting for Opus 5.5 achieves a higher score at a lower cost per attempt than the max setting on GPT-6 Astra.
- The presenter claims that recent models across multiple labs had developed unnatural, jargon-heavy speech (frequently overusing terms like "smoke test"), which he claims Anthropic fixed in Opus 5.5 with more human-like, concise communication.
- The presenter notes Claude's voice mode and tool harness are currently still inferior to ChatGPT's advanced voice capabilities [10:08].
Notable quotes
- [00:00] "Claude Opus 5.5 is the best AI model ever released, and it's the one you should be using for pretty much everything right now."
- [02:35] "This is like the trifecta of great: speed, intelligence, and cost—all better, all improved, all like best-in-class."
- [04:54] "They fixed it with Opus 5.5... It talks human again."
Assessment
This is an independent creator review and hands-on impressions video featuring actual coding outputs, terminal sessions, and software built with early access to Claude Opus 5.5. While the creator demonstrates real generated games and applications, the evaluation is highly enthusiastic and includes a sponsored segment for third-party Claude prompts/skills.
Described by gemini-3.8-flash on 2026-09-29 from the video's audio and frames.