Is Claude Mythos “Terrifying”? (According to Experts: No.)
Cal Newport · 2026-05-02 · community · 92,333 views
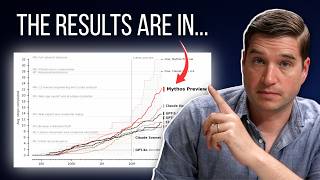
What's in the video
Description written by Gemini, which watched and listened to the whole video.
Summary
Author and computer science professor Cal Newport hosts an "AI Reality Check" episode of his Deep Questions podcast examining the hype surrounding Anthropic’s Claude Mythos. Newport analyzes independent evaluations and the UK AI Security Institute (AISI) report to argue that Mythos represents an incremental improvement in cybersecurity rather than an unprecedented, existential breakthrough.
What is shown
- Thomas L. Friedman’s New York Times column headline: "Anthropic’s Restraint Is a Terrifying Warning Sign" (April 7, 2026) [00:28].
- A movie clip from WarGames (1983) featuring the WOPR supercomputer [01:07].
- The 2024 research paper LLM Agents can Autonomously Exploit One-Day Vulnerabilities on arXiv [03:14].
- A post on X by Hugging Face CEO Clem Delangue demonstrating open-weight models matching Mythos's bug-finding claims [05:40].
- A post on X by security researcher Stanislav Fort evaluating Mythos showcase vulnerabilities [06:46].
- The UK AI Security Institute (AISI) report: Our evaluation of Claude Mythos Preview’s cyber capabilities (April 13, 2026) [09:33].
- Charts from the AISI report detailing:
- Beginner CTF Challenge Performance by Model across token budgets and skill levels [09:42].
- Advanced CTF Challenge Performance (50M token budget) [11:28].
- "The Last Ones" simulated corporate network attack (32-step sequence) tracking average steps completed [12:04, 12:36].
Claims & numbers
- The presenter notes that a 2024 study showed GPT-4 autonomously exploited 87% of one-day vulnerabilities compared to 0% for GPT-3.5 [03:28].
- The presenter cites Anthropic’s Opus 4.6 release notes claiming it identified over 500 exploitable zero-day vulnerabilities [04:10].
- Citing Delangue and Fort, the presenter states that 8 out of 8 open-weight models (including a 3.6B parameter model costing $0.01 per million tokens and a 3B model) independently discovered Mythos’s showcase FreeBSD zero-day [06:03, 07:00].
- Citing Bruce Schneier: "You don't need Mythos to find the vulnerabilities they found" [07:22].
- Citing AISI benchmark results:
- On the advanced CTF task, Claude Mythos Preview scored on par with or marginally above GPT-5.4, Codex 5.3, and Claude Opus 4.6 [11:42].
- On "The Last Ones" 32-step cyber range, Claude Opus 4.6 completed an average of 16 steps, whereas Claude Mythos Preview reached 22 steps [12:53].
- The presenter claims Anthropic’s cybersecurity benchmark scores increased incrementally from approximately 66.6% to 83.1% [20:58].
- The presenter mentions that Claude Code’s source code leaked via an npm package map file roughly a week prior to Mythos's reveal, and security researchers immediately found vulnerabilities in it [18:00].
Notable quotes
- "Basically, the mood of much of the internet right now about Claude Mythos is that Anthropic just invented the WOPR supercomputer from the 1983 Matthew Broderick movie WarGames." [00:56]
- "The claim is not LLMs are bad at finding security bugs. The claim is Mythos doesn't seem, at least in this testing, to indicate that it has a profoundly more advanced capability to do this than existing models." [07:32]
- "We have to essentially stop taking anything that the AI companies say seriously until we have independently verified it." [22:48]
Assessment
This is a critical commentary and analysis episode by Cal Newport discussing the reception of Claude Mythos. Newport does not run live software benchmarks himself, instead synthesizing published research papers, community replications on X, and the UK AISI report to deconstruct corporate marketing narratives.
Described by gemini-3.8-flash on 2026-09-29 from the video's audio and frames.