Why AI Agents Need More Than One Model
NVIDIA YouTube 11,972 views as of 8 November 2026
Description
Description written by Gemini from the videoGemini 3.8 Flash, 29 September 2026
Summary
This explainer video from NVIDIA illustrates the “system of models” architecture for enterprise AI agents, focusing on model routing and local specialization. It demonstrates how Glean uses a specialized model (Waldo), post-trained on NVIDIA Nemotron 3 Nano, to retrieve enterprise context and route queries between local and frontier cloud models.
What is shown
- [00:00 - 00:18] Multi-model selectors in various enterprise AI interfaces including Together AI, Perplexity, ChatGPT, Claude, and Glean.
- [00:19 - 00:36] Architecture diagrams demonstrating query routing between local on-premises models and cloud-based frontier models.
- [00:37 - 00:44] Enterprise search demo in Glean querying company policy: “What’s our reimbursement policy for home office equipment?”
- [00:45 - 01:28] Workflow schematic detailing Glean’s “Waldo” router (post-trained on NVIDIA Nemotron 3 Nano), showing how simple queries are resolved directly via open models while complex tasks are routed to high-parameter frontier reasoning models.
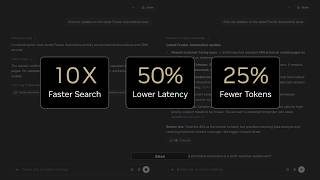
- [01:29 - 01:42] Side-by-side response comparison of “Waldo Off” vs. “Waldo On” for the query “Give me updates on the latest Frasier Automotive issue”, showing substantial response time differences.
- [01:43 - 01:53] A multi-step structured reasoning task evaluated in Glean synthesizing company data against public product trends.
Claims & numbers
- Glean’s Waldo is post-trained on NVIDIA Nemotron 3 Nano.
- The narrator and on-screen metrics claim that routing with Waldo achieves:
- 10X faster enterprise search.
- 50% lower latency.
- 25% fewer tokens consumed.
- No reduction in answer quality.
Notable quotes
- [00:01] “Intelligence isn’t one-size-fits-all. AI agents are built with many models, each bringing different strengths to the work.”
- [00:45] “Waldo, a specialized model post-trained on NVIDIA Nemotron 3 Nano, gathers context across sources like support tickets, Slack, and survey data.”
- [01:31] “Routing lets Glean search enterprise context 10 times faster. This translates to 50% lower latency and 25% fewer tokens, with no reduction in answer quality.”
Assessment
This is an official promotional product showcase and architectural explainer produced by NVIDIA in partnership with Glean. The demonstrated performance enhancements (10x search speed, 50% latency reduction) represent vendor-selected benchmarks shown in a polished, edited UI demonstration.
Described by gemini-3.8-flash on 2026-09-29 from the video’s audio and frames.