Introducing Microsoft-Decision-1
Satya Nadella (@satyanadella)Xlaunch video1,642,030 views as of 12 October 2026
Why it is here
Satya Nadella’s launch post for Microsoft-Decision-1 with a 10-second video (~1.64M views, fxtwitter, Oct 12); the official announcement of the model.
Description
Description written by Gemini from the videoGemini 3.8 Flash, 12 October 2026
Summary
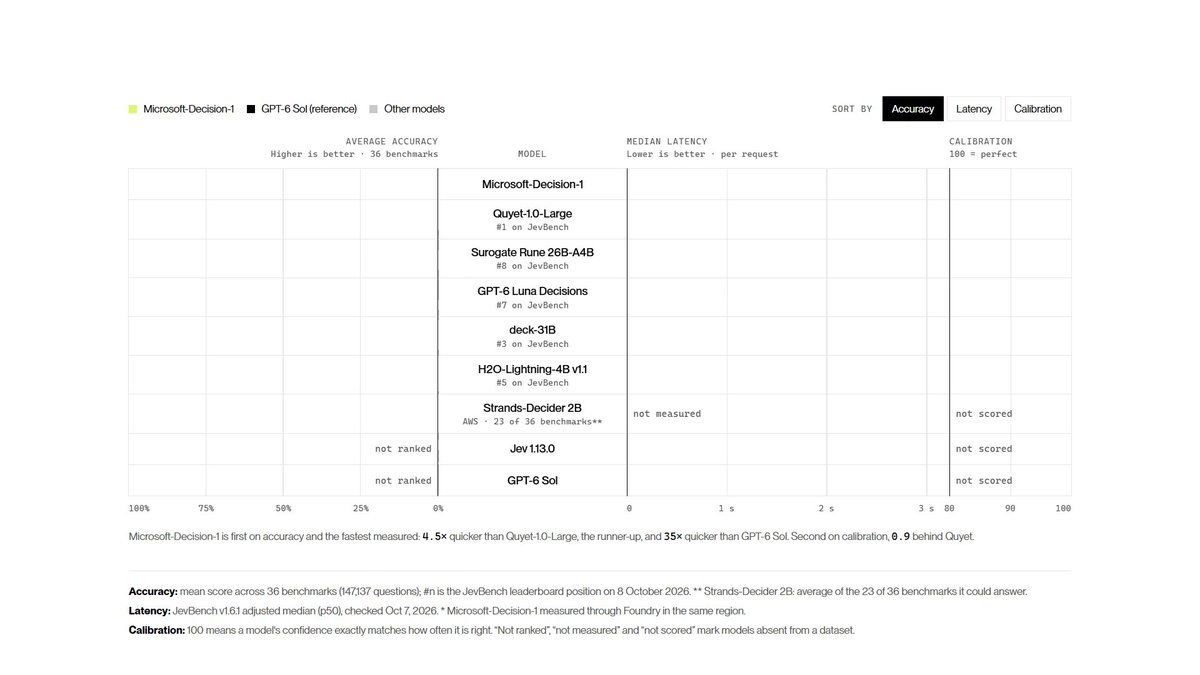
This video is a silent graphic presentation shared by Satya Nadella announcing the launch of Microsoft-Decision-1. It presents a benchmarking dashboard comparing Microsoft-Decision-1 against competing decision models on accuracy, latency, and calibration across 35 benchmark evaluations.
What is shown
- [00:00–00:02] An interactive benchmark chart sorted by Accuracy, ranking Microsoft-Decision-1 at the top with 83.5% average accuracy across 35 benchmarks, followed by Qwen3.10-Large (81.9%), Surrogate Ruixi-26B-A4B (79.7%), GPT-6 Luna Decisions (79.4%), dock-31B (77.9%), H2O-Lightning 4B v1.1 (77.2%), and Strands-Decider 2B (50.8%).
- [00:03–00:04] The dashboard toggling to sort by Latency, ranking Microsoft-Decision-1 first with an adjusted median latency of 210 ms (p50: 85 ms, p95: 520 ms), followed by H2O-Lightning 4B v1.1 (210 ms), Jev 1.1.0 (260 ms), Surrogate Ruixi-26B-A4B (310 ms), Qwen3.10-Large (380 ms), GPT-6 Luna Decisions (388 ms), dock-31B (480 ms), and GPT-6 Sol (3.86 s).
- [00:05–00:07] The dashboard sorting by Calibration (scaled to 100 as perfect), ranking Qwen3.10-Large first at 93.1, followed closely by Microsoft-Decision-1 in second place at 92.2, H2O-Lightning 4B v1.1 at 91.4, Surrogate Ruixi-26B-A4B at 89.8, GPT-6 Luna Decisions at 89.1, and dock-31B at 83.5.
- [00:08–00:09] The interface toggling back to the Accuracy sort view.
Claims & numbers
- Accuracy: The graphic claims Microsoft-Decision-1 achieves 83.5% average accuracy across 35 benchmarks in the MS-D1 question set, ranking first overall.
- Latency speedup: The graphic claims Microsoft-Decision-1 is “the fastest measured,” being 4.5× quicker than runner-up Qwen3.10-Large and 15× quicker than GPT-6 Sol (reporting a median latency of 210 ms with p50 of 85 ms and p95 of 520 ms measured through Azure Foundry).
- Calibration: The graphic claims Microsoft-Decision-1 scores 92.2 on calibration, finishing second overall, 0.9 points behind Qwen3.10-Large (93.1).
Notable quotes
- [00:01] “Microsoft-Decision-1 is first on accuracy and the fastest measured, 4.5× quicker than Qwen3-10-Large, the runner-up, and 15× quicker than GPT-6 Sol. Second on calibration, 0.9 behind Qwen.” (on-screen text)
- [00:01] “Accuracy: mean score across 35 benchmarks (MS-D1 question set), in the Jev-style task leaderboard posted in October 2026.” (on-screen footnote)
- [00:02] “Calibration: 100 means a model’s confidence exactly matches how often it is right.” (on-screen footnote)
Assessment
This is an official promotional infographic video presenting comparative evaluation results. It presents model metrics and benchmark comparison slides rather than a live code demo or developer interactive session.
Described by gemini-3.8-flash on 2026-10-12 from the video’s audio and frames.