Sonnet 5.5 vs Opus 5.5 vs Sonnet 5: A thorough comparison using the creation of famous paintings,...
AI時短ラボ · 2026-09-29 · review · 6,986 views
What's in the video
Description written by Gemini, which watched and listened to the whole video.
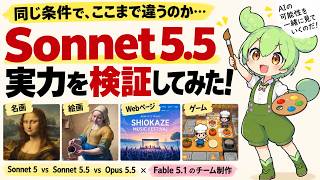
Summary Presented by Japanese AI channel AI時短ラボ (featuring VOICEROID/Voicevox avatars Zundamon and Shikoku Metan), this video evaluates whether Anthropic’s newly released Claude Sonnet 5.5 represents a genuine upgrade over Sonnet 5, while benchmarking both against Claude Opus 5.5 and Claude Fable 5.1. The presenters test the models across four independent creative programming tasks in Claude Code (recreating the Mona Lisa and Vermeer's The Milkmaid via programmatic brush engines from memory, coding an event website, and coding a cooking game) followed by a collaborative game development project directed by Fable 5.1.
What is shown
- [00:24] Setup & Methodology: Replicating Anthropic's developer blog experiment (from 2026-09-28) using Claude Code v2.1.284 with thinking effort set to
highacross Sonnet 5, Sonnet 5.5, and Opus 5.5, instructing them to paint from memory by writing Python brush stroke engines without viewing reference images. - [01:57] Task 1 – Mona Lisa Recreation:
- Sonnet 5 produces an unrecognizable abstract figure despite 11 revisions and 17,296 brush calls.
- Sonnet 5.5 finishes fastest in 17m 58s (15,800 brush calls), producing distinct hair, folded hands, and background terrain.
- Opus 5.5 correctly recalls subtle architectural elements (an arch column on the far right) and performs 48,960 brush calls. Both 5.5 and Opus 5.5 use a coarse-to-fine painting strategy reminiscent of Hertzmann's 1998 SIGGRAPH algorithm.
- [04:10] Task 2 – Vermeer's The Milkmaid:
- Sonnet 5 renders a simplistic front-facing figure where milk appears as a solid stick.
- Sonnet 5.5 captures the correct angle and jug-to-bowl stream (73,811 calls), but notes in its self-evaluation that the wall basket floats and the skirt resembles legs.
- Opus 5.5 accurately reconstructs the room, wall basket, brass container, bread basket, and foot warmer in 34m 18s across 13 iterations.
- [05:25] Task 3 – Fictional Music Festival Website (Shiokaze Ongakusai 2026):
- Sonnet 5 finishes in 3m 26s ($0.58) with a generic layout and a bare-bones line map.
- Sonnet 5.5 adds custom sunset palettes, banner bunting, and 12 distinct band illustrations.
- Opus 5.5 designs an intuitive vertical dual-stage timetable where block height reflects set duration, plus an informative transit/venue map.
- [07:00] Task 4 – Overcooked-Style Action Cooking Game (Dotabata Kitchen):
- All three models independently select the title Dotabata Kitchen and produce playable games evaluated via automated 60-second input scripts.
- Sonnet 5.5 implements plate washing, burnt food mechanics, trash bins, and combo scoring.
- Opus 5.5 delivers a polished HUD with tip multipliers and sprint controls.
- [08:36] Cost & Token Efficiency Comparison: Detailed bar chart showing total API equivalent cost across all four tasks: Sonnet 5.5 ($7.02 / 9.33M tokens), Sonnet 5 ($9.01 / 23.10M tokens), and Opus 5.5 ($15.65 / 15.09M tokens).
- [10:34] Fable 5.1 Team Production: A collaborative Zelda-like game (Ruin of Echoes) directed by Fable 5.1 with a $50 API budget.
- Sonnet 5 creates 18 sound effects and 4 BGM tracks in 5 minutes for $0.52.
- Sonnet 5.5 is assigned QA/inspection but runs for ~2 hours ($10.65), encounters an authentication timeout, and is fired by Fable 5.1 for poor cost-effectiveness.
- Opus 5.5 takes over QA ($4.72), fixing room-clearing progression bugs.
- [14:22] A custom player agent demonstrates a complete run of the finished game in 1m 21s. Total project cost: $33.55.
Claims & numbers
- Official API pricing for Sonnet 5 and Sonnet 5.5 is identical at $2.00 per 1M input tokens and $10.00 per 1M output tokens (the presenter states).
- Fable 5.1's output token cost is 2.5 times that of Opus 5.5 and 5 times that of Sonnet 5 / 5.5 (the presenter states).
- Sonnet 5.5 had an effective total cost ~22% lower than Sonnet 5 ($7.02 vs. $9.01) because it required fewer conversational back-and-forth turns (81 vs. 186 API calls), drastically reducing re-read context tokens in Claude Code (the presenter states).
- The team production project finished under its $50 budget at $33.55: Opus 5.5 ($15.63), Sonnet 5.5 ($10.65), Fable 5.1 director ($6.74), and Sonnet 5 ($0.52).
- Sonnet 5.5's thinking effort defaults to
mediumin Claude Code, but was manually set tohighfor equal comparison (the presenter states).
Notable quotes
- [03:56] "回数は出来とは関係なかったのだ。筆を細かくすれば増えるだけの設計のつまみで…" (Zundamon: "The number of brush strokes had nothing to do with output quality. It's just a design knob that increases when you make the brush finer...")
- [10:19] "1回ずつは安くても、行ったり来たりが多いと高くつくのね。" (Shikoku Metan: "Even if each turn is cheap, frequent back-and-forth makes it expensive.")
- [12:06] "正解はクビにはされず、安く済ませたい雑用だけを押し付けられたのだ。" (Zundamon: "The correct answer is it wasn't fired; it was just dumped with all the cheap chores.")
Assessment This is an authentic, hands-on third-party review and benchmark using the official Claude Code CLI tool. The tests demonstrate concrete Python script generations, web applications, and playable HTML5 canvas games, with candid disclosure of limitations (such as image filters used in painting post-processing, audio composed without auditory perception, and an auth timeout ending Sonnet 5.5's QA run early).
Described by gemini-3.8-flash on 2026-09-29 from the video's audio and frames.