Claude Sonnet 5.5 is LIVE & Somehow Beating Opus 5.5
Chase AI · 2026-09-29 · community · 73,833 views
What's in the video
Description written by Gemini, which watched and listened to the whole video.
Summary
Chase from the channel Chase AI reviews Anthropic’s official blog release for Claude Sonnet 5.5, published on September 28, 2026. He evaluates the new model's benchmark performance, token pricing, inference speed improvements, and safety fallback mechanisms compared to Claude Sonnet 5 and Claude Opus 5.5.
What is shown
- [00:00] The Anthropic announcement page for Claude Sonnet 5.5 (dated September 28, 2026).
- [00:15] Headline text highlighting that Sonnet 5.5 runs over 30% faster and costs up to 30% less than Sonnet 5.
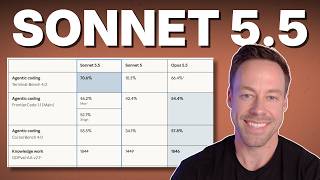
- [00:23] Benchmark evaluation table comparing Claude Sonnet 5.5, Sonnet 5, Opus 5.5, and GPT-6 Sol across agentic coding, SWE-bench 4.0, AA Briefcase 4.0, Humanity's Last Exam, OSWorld 2.1, and ChartQA 2.5.
- [01:10] TerminalBench 4.0 accuracy versus cost graph showing performance across effort levels (Low, Med, High, Max).
- [02:01] FrontierCode v1.0 accuracy versus cost per task graph showing degradation at "Max" effort level compared to "High".
- [02:39] Pricing breakdown table comparing Sonnet 5.5 ($2 / $10 per million input/output tokens) against Opus 5.5 ($4 / $20 per million input/output tokens).
- [03:02] Knowledge work evaluation section detailing GDPval-AA scores and early tester feedback from Slack.
- [03:46] Safeguards section outlining safety measures, biological distillation defenses, and cybersecurity fallbacks to Sonnet 5.
Claims & numbers
- Speed and cost: The presenter notes Sonnet 5.5 runs 30%+ faster, costs up to 30% less for most work compared to Sonnet 5, and token pricing is set at $2/million input and $10/million output (half of Opus 5.5's $4/$20). Cache reads are $0.20/million tokens and cache writes are $2.00/million tokens (versus $5.00 for Opus 5.5).
- TerminalBench 4.0: The presenter highlights Sonnet 5.5 scoring 70.6% at max effort ($12.54/attempt), outperforming Opus 5.5 (66.4% at $11.24/attempt) and Sonnet 5 (10.3%).
- FrontierCode v1.0: Sonnet 5.5 achieves 46.2% overall (versus 42.4% on Sonnet 5, 54.4% on Opus 5.5, and 49.3% on GPT-6 Sol); at "High" effort it hits 49.4% for $0.42, but drops to 46.2% at "Max" effort while cost spikes to $21.00.
- Other benchmarks: SWE-bench 4.0 scores 1844 (vs 1449 on Sonnet 5); AA Briefcase 4.0 scores 1811 (vs 1319 on Sonnet 5); CursorBench 4.0 reaches 55.1%; Humanity's Last Exam scores 64.5%; ChartQA 2.5 reaches 86.6%.
- Safeguards and fallbacks: High-risk cybersecurity requests fall back to Claude Sonnet 5 (or Opus 4.8 for Opus tier), and anti-distillation safeguards apply to biology queries.
Notable quotes
- [00:47] "In fact, agentic coding on the TerminalBench 4.0 test, it actually beats out Opus 5.5."
- [02:22] "Where you push it to max, it can kind of go crazy with the cost... Max doesn't always mean you're getting a better outcome."
- [04:16] "In the Sonnet, it falls back to Sonnet 5, which is pretty tough because Sonnet 5 isn't that great."
Assessment
This is a third-party commentary and analysis video walking through Anthropic's published release notes and benchmark tables on their website. The presenter does not run independent live benchmarks during the video, relying entirely on the data and graphs provided in Anthropic's announcement post.
Described by gemini-3.8-flash on 2026-09-29 from the video's audio and frames.