I Had Opus 5.5 Build me the Same App at Every Effort Level
Nate Herk | AI Automation · 2026-09-25 · community · 236,372 views
What's in the video
Description written by Gemini, which watched and listened to the whole video.
Summary
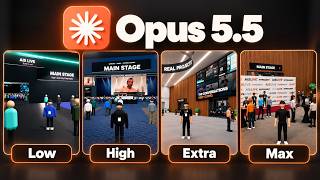
Nate Herk evaluates Anthropic's Claude Opus 5.5 model by issuing the exact same autonomous coding prompt across all six available effort settings: Low, Medium, High, Extra, Max, and Ultracode. The task requires building a fully walkable, third-person 3D web application recreating the physical venue and recorded content of the virtual AIS Live conference using 105 GB of video assets. After walking through each generated 3D world and analyzing cost, runtime, tokens, and verification checks, Herk concludes that the "Extra" effort setting produced the best overall result.
What is shown
- Prompt and Setup [00:44]: Displays
PROMPT.mdin the Claude Code interface, instructing the agent to build a 3D walkable conference experience using Three.js and assets from a 105 GB Frame.io folder. - Low Effort Result [01:47]: A sparse, overexposed 3D environment with floating chairs, static presentation slides instead of videos, and glitching attendees that disappear on approach.
- Medium Effort Result [04:21]: Introduces branded UI badges, working embedded video players for workshop rooms and sponsor booths, and an audience-filled main stage.
- Sponsor Segment [07:31]: Demonstration of Hostinger Connector deploying generated web apps directly from code editors (VS Code, Cursor, Claude Code).
- High Effort Result [08:26]: Adds an outdoor arrival plaza with speaker banners, sliding automatic doors, an attendee passport tracking system, live captioning, and VIP breakout rooms.
- Extra Effort Result [11:17]: Features interactive attendee speech bubbles, a working photo booth step-and-repeat wall that captures pictures, and seated VIP workshops with readable worksheets.
- Max Effort Result [13:55]: Introduces an opening fly-in camera sequence, an interactive AV switcher board at the main stage, an escalator, and a basketball mini-game in the expo hall, though suffering from awkward walking physics and visual clipping.
- Ultracode Effort Result [17:52]: Includes a badge/wristband gate check system, full-screen interactive slide decks, and downloadable event photos.
- Comparative Analysis & Charts [22:48]: A dashboard comparing runtime, API billing cost, token usage, verification checks, and cost per check across all six effort tiers.
Claims & numbers
- The presenter tests six effort levels for Opus 5.5 with the following recorded metrics:
- Low: 16m 43s runtime, $3.91 API cost, 191.3K tokens, 22 checks, 0 questions asked.
- Medium: 1h 13m runtime, $12.44 API cost, 419.2K tokens, 23 checks, 0 questions asked.
- High: 1h 7m runtime, $16.31 API cost, 509.3K tokens, 22 checks, 1 question asked (the only run to prompt the user).
- Extra: 1h 31m runtime, $25.92 API cost, 733.7K tokens, 34 checks, 0 questions asked.
- Max: 2h 28m runtime, $50.38 API cost, 1.18M tokens (hit auto-compaction threshold), 51 checks, 0 questions asked.
- Ultracode: 1h 35m runtime, $18.69 API cost, 606.2K tokens, 42 checks, 0 questions asked.
- The presenter states that Max effort was 12.9× more expensive than Low effort, ran 2.3× more verification checks, and that all six sessions combined cost $127.65 in API fees [22:49].
- The presenter claims none of the six runs initiated sub-agents, even in Ultracode [14:41, 22:31].
Notable quotes
- "So in this video, I gave Opus 5.5 the same exact prompt, and I ran it on every single effort level, and we're going to be comparing the results." [00:20]
- "Ultracode, it's just felt weird. It's felt a little buggy... It did quite a few more checks than these other ones, but for some reason, it just didn't feel right." [22:08]
- "So my winner here is definitely going to be Extra. Extra did a phenomenal job. It was about half the run time and half the cost of Max." [25:36]
Assessment
This is a genuine, hands-on empirical review and comparative benchmark comparing the outputs of Claude Opus 5.5 across different reasoning effort settings in an agentic coding environment. All demonstrations show real local browser builds and live telemetry logs without synthetic cuts or misleading claims.
Described by gemini-3.8-flash on 2026-09-29 from the video's audio and frames.