I Tried NEW Sonnet 5.5 on 27 Coding Prompts
AI Coding Daily YouTube 18,491 views as of 23 October 2026
Description
Description written by Gemini from the videoGemini 3.8 Flash, 29 September 2026
Summary
Povilas Korop of AI Coding Daily reviews Anthropic’s newly released Claude Sonnet 5.5 by running it through his standardized multi-project coding benchmark suite across different reasoning effort levels. He demonstrates the benchmark runs, analyzes the resulting scores and costs on his LLM Coding Leaderboard, tests bug-hunting capabilities on a Laravel project, and compares the model’s speed and pricing against Claude Opus 5.5 and OpenAI models.
What is shown
- [00:00 - 01:05] Official launch posts on X from Anthropic and Addy Osmani announcing Claude Sonnet 5.5 (>30% faster, up to 30% cheaper).
- [00:15 - 00:35] Previous leaderboard standings showing the older Claude Sonnet 5 ranked #42 out of 55 with 44.55 points ($0.79 / 3:29 per prompt).
- [01:10 - 02:34] Terminal benchmark execution on Laravel offline-sync, Dart/Flutter transaction feed, and Go shipping-quote projects using
claude-sonnet-5-5on “medium” effort, showing runtimes under 1 minute and costs around $0.13–$0.25 per prompt. - [02:55 - 03:12] Terminal benchmark execution on “high” effort (
effort=high), showing ~2-minute execution times, zero failed tests, and costs around $0.29–$0.35. - [03:58 - 04:25] Updated LLM Coding Leaderboard (September 29th, 2026):
- Sonnet 5.5 (High): Rank #4, 56.18 points, $0.34 average cost, 1:53 average time.
- Sonnet 5.5 (Medium): Rank #10, 53.46 points, $0.20 average cost, 0:58 average time.
- [06:40 - 07:44] Testing the experimental
xhigheffort level on terminal runs; runtimes increase to ~5–6 minutes and costs rise to $0.80–$1.57. - [07:57 - 08:22] Devin interface showing model selection where Devin sets
Claude Sonnet 5.5 Highas the default reasoning level. - [08:23 - 08:51] Terminal evaluation of
effort=low, showing negligible cost or time savings compared to medium, but lower test pass rates. - [10:17 - 10:48] Posts on X from Kun Chen and the official
@claudeaiaccount announcing Claude Haiku 5.5 arriving in the coming weeks. - [11:58 - 13:30] A new “Bug Hunt Leaderboard” evaluation prompt (
audit-v2.md) and results table: Opus 5.5 leads at 81.3, while Sonnet 5.5 (Medium) scores 68.8 (13/16 natural bugs, 3/5 planted bugs, 17 findings) in 2:05 at $0.63.
Claims & numbers
- Anthropic states Sonnet 5.5 runs over 30% faster and costs up to 30% less than Sonnet 5 for most work (quoted at [00:54]).
- On the presenter’s leaderboard, Sonnet 5 previously scored 44.55 points, costing $0.79 with a 3:29 average runtime [00:24].
- Testing 24 prompts on medium effort consumed only ~30% of the 5-hour rate limit on the $20 Anthropic plan [02:35].
- On the refreshed leaderboard (September 29, 2026), Sonnet 5.5 (High) achieved 56.18 points ($0.34 / 1:53 prompt average), ranking 4th behind Opus 5.5 and GPT-6 Astra [04:06].
- Sonnet 5.5 (Medium) achieved 53.46 points ($0.20 / 0:58 prompt average), becoming the first model on his leaderboard to break the under-1-minute average completion threshold [04:12, 05:15].
- On
xhigheffort, runtimes jumped to 5:22–6:01 and costs rose to $0.81–$1.57, which the presenter claims falls off the Pareto frontier [07:11, 07:45]. - In the bug-hunting audit benchmark, Sonnet 5.5 placed third behind Opus 5.5 and Grok 4.6, taking 2:05 and costing $0.63 [12:50, 13:17].
Notable quotes
- “Sonnet 5.5 medium is the first model ever on my leaderboard to surpass under 1 minute average.” [05:15]
- “Can you imagine that jump in quality? So Sonnet 5 was scoring like 2, 3 points out of 5... and the time was... it’s incomparable.” [04:28]
- “My overall approach now is: Opus plans, Sonnet implements... and then your role is to keep up with them with your ideas, prompting, and code review.” [10:24]
Assessment
This is an authentic, independent benchmark review video demonstrating real evaluation runs and leaderboard data. The testing methodology across automated test suites, code quality grading, and bug-hunting audits is clearly displayed and fully executed on screen.
Described by gemini-3.8-flash on 2026-09-29 from the video’s audio and frames.
Related
More videos on this
-
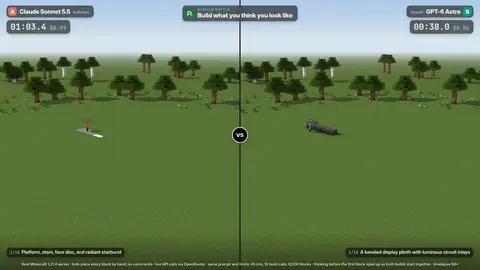
“Build what you think you look like”: Claude Sonnet 5.5 vs GPT-6 Astra
Siya (@siyabuilt)7,259,229 views as of 27 Oct
-
Introducing Claude Sonnet 5.5
Claude4,403,927 views as of 27 Oct
-
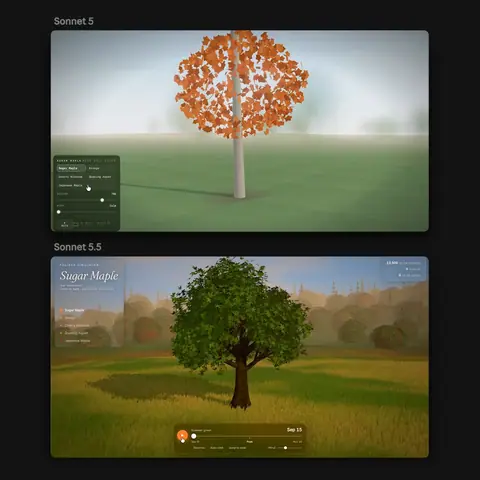
Fall foliage simulator made with Sonnet 5 vs Sonnet 5.5 (official @claudeai launch-thread video)
Claude (@claudeai)755,645 views as of 26 Oct
-
Gemini 4, GPT 6.1, Dots, Claude Sonnet 5.5, Ideogram 4.5, Flux 3: AI NEWS
AI Search373,606 views as of 31 Oct