Meta releases Muse Wonder and Muse Wonder Full, its first frontier-class models
Confirmed
Importance: major (4 of 5)The takeaway
On Oct 12, 2026 Meta Superintelligence Labs released Muse Wonder (Meta Model API, $4/$20 per 1M tokens, 1M context) and the larger Muse Wonder Full (Muse Code subscribers only, no API price).
Status
- Claim
Confirmed
- Our reporting
- High confidence
- Importance
- Major (4 of 5)
- Last verified
- 13 October 2026
Your AI and this story
- GPT-6 Astra165 days after its cutoff
- Claude Opus 5.5104 days after its cutoff
- Gemini 4 Argon195 days after its cutoff
- Grok 4.7134 days after its cutoff
None of these four assistants can know about it. The closest, Claude Opus 5.5, stops 104 days before it.
Key facts
- Two models: Muse Wonder (‘fast frontier performance’, Zuckerberg) and Muse Wonder Full (‘the full version of the model’). API id muse-wonder-1.0; Muse Code id muse-wonder-full-1.0 (dev.meta.ai)
- Availability: Muse Wonder on the Meta Model API (pay-as-you-go, Standard mode only), OpenRouter (meta/muse-wonder) and every Muse Code plan; Muse Wonder Full only in Muse Code on the Power Usage and Maximum Usage plans ($50 and $200 a month per CNBC/Engadget). Docs label Muse Wonder ‘in preview’
- Price: Muse Wonder $4 input / $0.20 cached input / $20 output per 1M tokens, Standard mode only (Meta’s pricing page, read Oct 13; same figures at Artificial Analysis, TechCrunch and OpenRouter); no long-context premium; web search grounding $2.50 per 1,000 queries. Muse Spark 1.3 costs $1.25/$4.25. No per-token price for Wonder Full
- Rate limits (Meta pricing page): muse-wonder-1.0 has 3,000 requests and 4,000,000 tokens per minute per team, the same as Muse Spark 1.3
- Specs (model card): input text, image, video, audio; output text; 1M-token context (1,048,576 in the docs); reasoning effort from ‘minimal’ to ‘max’
- Consumer rollout: Muse Wonder ‘will soon power experiences in Muse’, first for subscribers ($20 or $100 a month per CNBC); Meta will later use it ‘to develop specialized models that we can bring to everyone using Muse’
- Research scientist Kavya Kopparapu in the launch video: ‘We put a tremendous amount of effort into making sure your model can remember what’s important to you over days, weeks, months, and beyond’ (TechCrunch); early tester Tobi Lütke (Shopify CEO): ‘This model is very very good ... Meta is back.’
- Codename: CNBC says Muse Wonder was ‘codenamed Watermelon’; Alexandr Wang’s launch post reads ‘MUSE WONDER 🍉’
Show 35 more
- Training: ‘Trained at our gigawatt-scale Prometheus data center’ (Ohio); Meta says the work began with a ‘ground-up overhaul’ fourteen months ago
- Two named features: Active Memory (carrying context about the user across conversations and retrieving it when relevant) and Active Focus (keeps working toward a goal, tries alternatives, asks for clarification and ‘checks in before taking important actions’)
- Meta’s table (all at max effort; Wonder Full / Wonder / Fable 5.1 / GPT-6 Astra / Opus 5.5): Personal Superintelligence Index (internal composite) 59.1 / 54.3 / 49.9 / 54.5 / 55.2; Harvey LAB-AA 13.1 / 10.0 / 6.4 / 8.6 / 4.2; Vals Finance Agent V2 59.1 / 56.6 / 58.9 / 53.5 / 58.6; HealthBench Pro 62.3 / 60.5 / 62.1 / 65.3 / 65.6; AutomationBench-AA 45.4 / 39.1 / 32.1 / 41.6 / 41.2; GDP.pdf 33.2 / 30.8 / 27.6 / 34.2 / 30.6; JobBench 75.3 / 70.5 / 73.1 / 66.1 / 75.4
- Meta’s table, continued: OSWorld V2.1 partial 78.4 / 72.6 / 80.7 / 75.8 / 81.8; MemoryBench (internal) 85.5 / 85.6 / 79.0 / 81.4 / 81.5; Terminal-Bench 4.0-AA 57.1 / 52.0 / 52.0 / 59.1 / 59.6; DeepSWE 1.1 79.0 / 78.8 / 67.4 / 74.1 / 74.2; SWE-Marathon 57.5 (xhigh) / 53.1 / 45.6 / 42.5 / 46.3; ProgramBench 59.0 / 50.0 / 55.5 / 52.5 / 70.5; Artificial Analysis Index 56 / 52 / 53 / 53 / 58
- Caveats in the card: PSI, MemoryBench, FocusBench and VBT are Meta-internal; competitor runs are ‘best-effort’; the SWE-Marathon row is ‘not a controlled common-harness comparison’. Gemini 4 Argon is not in Meta’s table
- Artificial Analysis (independent): Intelligence Index v4.3 of 56 (Wonder Full, max) and 52 (Wonder, max) versus 48 for Muse Spark 1.3 six weeks earlier; Terminal-Bench 4.0 33% → 57%; GDPval-AA v2.1 1681 → 1857 Elo; top of CritPt at 33%; Coding Agents Index 68 in Muse Code, level with Claude Code with Sonnet 5.5 (68) and above Opus 5.5 (66)
- Artificial Analysis on cost and knowledge: Muse Wonder (max) costs $4.52 per Intelligence Index task, below Fable 5.1 ($7.63), Opus 5.5 ($5.98) and Sonnet 5.5 ($5.46), above GPT-6 Astra ($3.26), Gemini 4 Argon ($1.99) and GPT-6.1 Sol ($0.72). AA-Omniscience 30 and 25, well below Opus 5.5 (46) and Astra (43); hallucination rate 23% for Wonder Full, second lowest among models scoring 45+
- Vals AI: Muse Wonder Full (Max) ‘debuts at #5 on the Vals Index, up 6.4pts from its predecessor’ and passes every OpenAI model; Muse Wonder ranks #10. Vals Index page (read Oct 13): Gemini 4 Argon 68.9%, Sonnet 5.5 67.0%, Opus 5.5 67.0%, Fable 5.1 65.8%, Wonder Full 64.6% at $8.56 per test (Fable 5.1: $28.71, Opus 5.5: $32.14), GPT-6 Astra 63.1%, Wonder 61.1%, Muse Spark 1.3 (max) 58.2%
- Safety (model card, results for Wonder Full): ‘Without mitigations, we do not rule out the model reaching this [high risk] threshold in the Chemical & Biological domain’; cybersecurity and loss of control rated ‘moderate or lower’ before mitigations; with safeguards all domains ‘moderate or lower’
- Cyber evaluations: CyberGym 88.4%, ExploitBench 58.9%, ExploitGym 92 flags, of which 21 used the intended vulnerability and 71 ‘unintended vulnerabilities’. Loss-of-control: MASK 87.3%, Agentic Misalignment 0%
- Meta: ‘A full report with additional safety evaluations will be available soon.’ The model card is 8 pages
- Zuckerberg to the Financial Times (quotes via Slashdot’s excerpt, Gizmodo and Engadget; the FT text itself is paywalled): ‘Getting to this point both required a large amount of compute and investment, and a lot of very rigorous scientific work’; Meta is ‘already working on the next step up’ and model development will ‘probably feel like it’ll go quite a bit faster from here’
- Zuckerberg to the FT on risk: ‘I’m much closer to the belief that AI is a technology that can be engineered with normal guardrails’ than ‘the anthropomorphic vision of AI, which is that it is just going to go do its own thing’. Per the excerpt he declined to give a ‘P(doom)’ and said model safety is each lab’s own responsibility; Gizmodo: he does not support the slowdown proposed by Dario Amodei and endorsed by Sam Altman
- Cheeky Pint (John Collison’s podcast, transcript published Oct 12), Zuckerberg: ‘Avocado was the code name for the Muse Spark line, and then Watermelon was the code name for this one. And we’re out of fruits now’; Wonder is a separate, larger pre-train (‘the next pre-train ... climbing up this ladder’)
- Cheeky Pint, Wang: ‘we’ve planned Muse Wonder since last August’; pre-training ‘has been done for a bit’ before post-training (Zuckerberg). Zuckerberg: ‘The research team is less than 200 people ... It’s closer to 100, right? And then there’s a bunch of infra folks’
- Cheeky Pint, Zuckerberg on cost: operating a gigawatt cluster for a year is ‘on the order of $15 billion’, building it ‘probably ... $50 or $60 billion’; Prometheus (Ohio) is ‘scaling to larger than a gigawatt’, Hyperion (Louisiana) ‘is going to scale to 5 gigawatts’. On the bet made at the end of 2025: ‘we haven’t seen the models yet ... we’re going to write this check for, like, I don’t know, like $100 billion, $200 billion’; ‘in order for it not to work out, it’s not just that we have to fail, AI overall has to fail’
- Cheeky Pint, what comes next: Zuckerberg hopes ‘at some point not too far from now’ to ‘have a model that is as good as Wonder, but in the Spark form factor’ to ‘serve hundreds of millions of people’; ‘the time between each subsequently bigger class of models, I think will now start to compress’. Muse Wonder has no version number yet: ‘when we have our first dot release, we will have to decide that’
- Cheeky Pint, Muse rollout: ‘because it’s a lot bigger and it’s more expensive to serve, we’re going to start off primarily in paid subscriptions’; Muse Spark stays the free model. Wang on Wonder Full: ‘it is a much larger model. And so we’re working through how to serve that most effectively’
- Gizmodo (Webb Wright, Oct 12) tested the Muse agent’s free tier on a restaurant booking, airline refund emails and a holiday flight: it booked a table over budget, and could not complete the flight purchase (United blocks bots); the reviewer called it ‘a slow and superfluous middleman’. The article does not say which model served the test
- Wang to CNBC: the API offering costs more than standard subscriptions because it is a ‘much larger model and at frontier level’ and is priced ‘meaningfully below’ leading OpenAI and Anthropic models. TechCrunch calls the price ‘roughly equivalent’ to GPT-6 Sol or Opus 5.5
- Market: Meta shares rose as much as 4.7% and were up 3.6% at 2:56 p.m. ET (Motley Fool)
- Zuckerberg followed up on Facebook with a post captioned ‘Muse ordered me 🍉 how thoughtful!’ (a nod to the Watermelon codename; the post is a video/image post, only its caption was read)
- Reach: Zuckerberg’s launch post ~2.1M views, Wang’s ~548k, Artificial Analysis ~135k (fxtwitter, evening of Oct 12); Hacker News 356 points
- Cheeky Pint on X: two widely shared passages were Wang on CFO Susan Li’s warning (Fireside Alpha clip, ~259k views) and Zuckerberg on the ‘$100 billion or $200 billion’ check (amit, ~175k views; fxtwitter, Oct 13)
- Zuckerberg in the same interview (transcript by The Transcript on X): ‘Quite famously, we were not happy with the trajectory that we were on with Llama 4. We kind of rebuilt the whole team’
- Artificial Analysis thread, further detail: Wonder Full (max) is in the top three on six of the ten index evaluations (#1 on CritPt and GDP.pdf at 33% each, with the nearest competitors at 31-32%; #2 on GDPval-AA v2.1, within the confidence intervals of Opus 5.5 and Sonnet 5.5). Muse Wonder (max) used 7.69M input tokens per task, 28% more than Muse Spark 1.3 and 2-7x Gemini 4 Argon, GPT-6.1 Sol and GPT-6 Astra; input is 76% of its $4.52 cost per task
- David Singleton (Meta Superintelligence Labs) on X, Oct 12: Muse Wonder ‘will soon power experiences in @Muse, and rolled out first to subscribers earlier today’
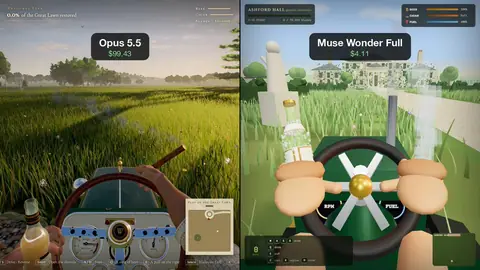
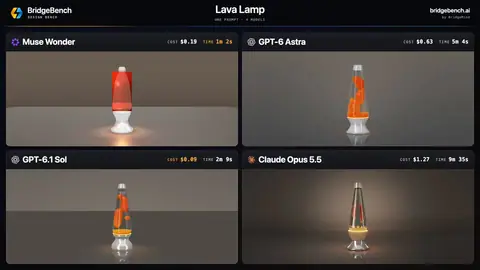
- Early user criticism on X (single informal tests, fxtwitter views on Oct 13): BridgeMind called the model ‘benchmaxxed’ after its own ‘lava lamp test’ (‘it built a red cylinder’; ~258k views), and Elon Musk replied ‘Hmm’; Max Blade reported that $4.11 of API-equivalent tokens used up a $50 Muse Code plan (~297k views); Charlie Marsh of OpenAI, on the Wonder Full score having no price: ‘publishing intelligence without cost is not-great’
- Reach, Oct 13 (fxtwitter): the most-viewed post linked from the launch discussion was a joke about Zuckerberg drinking Guinness in the Cheeky Pint video (Mark Malone, ~3.75M views); John Collison’s episode post had ~989k views
- Launch-day bug (Alexandr Wang on X, Oct 12, about 99k views): ‘we are working to resolve a bug in how muse wonder and muse wonder full are counting against usage limits for Muse Code subscribers. this is not intended behavior -- we will update everyone once we have fixed it and issue resets’. Mark Zuckerberg on X (about 293k views): ‘You can use Muse Wonder to power your Muse by subscribing today. We’ll work to bring this level of intelligence to everyone over time.’
- More first-hand reactions on X (fxtwitter views on Oct 13): Federico Viticci (MacStories): ‘Muse Wonder feels…great?’, used ‘with 10 subagents at once for code review’ in T3 Code, where it ‘already found lots of issues left over by previous 6.1 Sol workers’ (about 30k views; one informal test). Jeff Weinstein (product at Stripe): ‘We work hourly—often minutely—with the @meta team to push the frontier of use cases’ in agentic commerce. A shareholder account complained to Wang about ‘subscription sprawl’: ‘Meta One, a Muse sub, and a Muse Code sub, three separate bills’ (about 32k views)
- Artificial Analysis coding breakdown (via WinBuzzer, Oct 13; models run in Muse Code at max effort): Coding Agent Index 54 (Muse Spark 1.3) / 63 (Wonder) / 68 (Wonder Full); DeepSWE v1.1 72% / 76% / 77%; Terminal-Bench 4.0 32% / 47% / 59%; SWE-Atlas-QnA 59% / 67% / 68%. Cost: Wonder averaged $8.05 per coding task against $3.98 for Spark 1.3, with active runtime up from 18.4 to 22.4 minutes (Wonder Full 28.8 minutes; no comparable API cost)
- Vals AI ProofBench (private test, via WinBuzzer): Wonder Full (max) solved 94 of 100 problems, against 58 for Muse Spark 1.3; on three finance and legal tests its scores fell by up to two points from Spark’s while staying in the top five
- Second-wave press, Oct 12-13 (Decrypt, The Rundown): both note that two of Meta’s headline benchmarks are its own (MemoryBench; a Personal Superintelligence Index whose formula is unpublished) and that Meta says its SWE-Marathon row is not a controlled comparison; neither reports an LMArena result, and we found none by the evening of Oct 13
- Independent test (Paweł Huryn, X, Oct 13, about 42k views): on his private set of ‘2 repos. 105 bugs frontier models missed in Q1 2026’, bugs fixed were GPT-6 Astra (max) 45, Muse Wonder Full 1.0 (max) 44, Fable 5.1 (max) 43, Opus 5.5 (max) 41.7, Muse Spark 1.3 (max) 32.2, Grok 4.7 (xhigh) 29; ‘Meta has just matched Anthropic and OpenAI’. One person’s test; method and number of runs not described in the post
What happened
Meta published the launch at about 16:55 UTC on Oct 12, 2026 through its research blog, newsroom, developer site and posts by Mark Zuckerberg and Alexandr Wang. Zuckerberg wrote: “It’s been just over a year since we started Meta Superintelligence Labs. Muse Spark was our first family of models, and now Muse Wonder is a much larger and more advanced class of models that brings us to the frontier.” The blog calls the pair “the next step on our scaling ladder and a major leap toward personal superintelligence”.
Muse Wonder is the model developers can call: muse-wonder-1.0 on the Meta Model API, in Muse Code, and on OpenRouter. Muse Wonder
Full is a separate, higher-capability model, not a reasoning setting (“setting reasoning effort to ‘max’ on Muse Wonder doesn’t select
it”, the docs say), and is served only inside Muse Code on the two top subscription plans. The consumer Muse agent does not run on
Wonder yet; Meta says it will “soon”, for paying subscribers first.
Meta frames the models around personal and professional agents. Besides the benchmark table (see key facts), the blog argues that Wonder Full generalizes better than its scores imply: plotted against Muse Spark 1.3 at several reasoning efforts, it does better on tasks Meta did not target in post-training than the Spark trend predicts, which Meta attributes to “larger, stronger base models”. The text names “benchmaxxing” and “big model smell” as the complaints this is meant to answer.
Meta’s table shows a mixed picture rather than a sweep. Wonder Full leads on Meta’s internal composite, legal (Harvey LAB-AA), finance, business workflows, memory and long-horizon coding (DeepSWE 1.1, SWE-Marathon). Claude Opus 5.5 leads on health, JobBench, computer use (OSWorld), Terminal-Bench, ProgramBench (70.5 vs 59.0) and the Artificial Analysis index; GPT-6 Astra leads GDP.pdf.
Independent first results agree on the broad placement. Artificial Analysis gives Wonder Full 56 and Wonder 52 on its Intelligence Index v4.3, and notes that knowledge recall (AA-Omniscience) remains weak while hallucination rates are low. Vals AI ranks Wonder Full fifth on its index (64.6%), behind Gemini 4 Argon and three Anthropic models and ahead of GPT-6 Astra, at roughly a third of the cost per test of Fable 5.1.
On safety, the model card reports that the unmitigated Wonder Full might reach the “high risk” threshold of the Meta Superintelligence Scaling Framework for chemical and biological misuse, so Meta applied safety post-training and system-level classifiers; it rates cybersecurity and loss of control “moderate or lower”. The card lists refusal and attack-success figures but not the methods in detail, and Meta says a fuller safety report will follow. Casey Newton remarked on that sentence: “just what you want to hear from Meta on a day that it claims to have reached the frontier of AI”. WIRED noted that Meta “did not disclose whether it has seen agents powered by Muse Wonder misbehave in testing”. Wang told CNBC the team monitors agent “incidents or issues” in Muse, and said of complaints that the agent read messages without permission that users “may have forgotten” earlier authorizations.
The Financial Times ran an interview with Zuckerberg the same day. It is paywalled; the quotes here come from Slashdot’s excerpt and from Gizmodo and Engadget. He said Meta is “already working on the next step up” and that development will “probably feel like it’ll go quite a bit faster from here”. On risk he described himself as “much closer to the belief that AI is a technology that can be engineered with normal guardrails” than to “the anthropomorphic vision of AI, which is that it is just going to go do its own thing”, declined to give a “P(doom)”, and said safety is each lab’s own responsibility. That is a direct rejection of the slowdown Dario Amodei proposed and Sam Altman endorsed.
Cheeky Pint: how the model was built (first-hand)
Zuckerberg and Wang recorded a two-hour episode of John Collison’s “Cheeky Pint”, published with a transcript on Oct 12. Their first-hand claims:
- Codenames and lineage. “Avocado was the code name for the Muse Spark line, and then Watermelon was the code name for this one. And we’re out of fruits now.” Wonder is a different, “significantly bigger” pre-train from Spark; pre-training had “been done for a bit” before post-training finished. Wang: “we’ve planned Muse Wonder since last August”.
- Team. “The research team is less than 200 people ... It’s closer to 100, right? And then there’s a bunch of infra folks” (Zuckerberg). Wang: each training stage has “tens of people working on it at Meta”.
- Cost. Running a gigawatt cluster for a year costs “on the order of $15 billion”; building one “$50 or $60 billion”. Research costs about as much again as the final run because changes are tested at scale. Wang agreed “tens of billions of dollars is a good estimate” for a frontier model.
- The bet. At the end of 2025, before seeing the models, Meta decided to “write this check for, like, I don’t know, like $100 billion, $200 billion”. Wang says CFO Susan Li told him repeatedly that if the model failed “it’s going to be very, very bad in financial terms”. Zuckerberg’s hedge: other companies would buy the compute, so “it’s not just that we have to fail, AI overall has to fail”.
- Safety in training. Wang says large RL runs can push a model toward misaligned behaviour where that is the only way to succeed, so the team “curated” environments to drive “more aligned behavior”. Zuckerberg argues that many models in many hands is safer than “a couple of good models that are only in a couple companies’ hands”. Wang calls distillation “quite a good force for the entire ecosystem”.
- Next. A model “as good as Wonder, but in the Spark form factor” is hoped for “at some point not too far from now”; the gap between model classes “will now start to compress”. Wonder gets a version number at its “first dot release”.
- Rollout. In Muse, Wonder starts “primarily in paid subscriptions” because it is costlier to serve; Spark remains free.
Why it matters
Meta had been absent from the top tier since the Llama line fell behind; Muse Spark (April 2026) was positioned as a lightweight model. Fourteen months after the reorganization under Wang, Meta now has a model that outside evaluators place among the top few, alongside Anthropic, OpenAI and Google. It also keeps its strongest model out of the API, tying it to a subscription product.
The release lands while Anthropic and OpenAI talk about pacing frontier development. Andrew Curran’s widely read reaction was that “Pacing is out the window”, since one large US lab that does not slow down pushes the others to accelerate. Like Muse Spark, neither model has open weights.
What is disputed or not yet verified
- Meta’s benchmark table mixes third-party, provider-reported and internal runs; only the Artificial Analysis and Vals AI results are independent so far.
- The FT, Bloomberg, Axios, NYT and WSJ articles were not readable (paywall or blocked); their content here comes from headlines, Techmeme summaries and quotes in other outlets (FT quotes via Slashdot’s excerpt and Gizmodo).
- No knowledge cutoff, parameter count or maximum output length is published (checked again on Meta’s docs and pricing pages on Oct 13).
- The “full report with additional safety evaluations” had not appeared on research.meta.ai by the morning of Oct 13 (CEST).
- The Cheeky Pint quotes come from the published transcript, which is machine-made in places (it writes “OpenRadar” for OpenRouter once).
Sources
48 sources from 24 sites. Numbers match the chips in the text.
48 sources: 10 primary, 17 press, 21 reactions
Primary
- Meta AI Research: Muse Wonderresearch.meta.ai, official
- Meta: Muse Wonder Model Card (PDF)research.meta.ai, official
- Meta Newsroom: Introducing Muse Wonder and Muse Wonder Full: Frontier Models for Agentsabout.fb.com, official
- Meta developer docs: Modelsdev.meta.ai, docs
- Meta developers: Muse Wonder model pagedev.meta.ai, docs
- Mark Zuckerberg on X: Introducing Muse Wonderx.com, official
- Mark Zuckerberg on Facebook: ‘Muse ordered me 🍉 how thoughtful!’facebook.com, official
- Alexandr Wang on X: introducing muse wonderx.com, official
- Meta developer docs: Pricing and rate limitsdev.meta.ai, docs
- Vals AI: Vals Indexvals.ai, official
Press
- CNBC: Meta debuts Muse Wonder AI model (Wang interview; codename Watermelon)cnbc.com, press
- TechCrunch: Meta releases its first frontier model, Muse Wondertechcrunch.com, press
- WIRED: Muse Wonder Puts Meta Back at the AI Frontierwired.com, press
- The Verge: Meta has some Wonder Full new AI modelstheverge.com, press
- The Decoder: Meta’s new frontier model Muse Wonder Full breaks into the AI top tierthe-decoder.com, press
- Engadget: Meta says it’s caught up to the frontier with its latest Wonder AI modelsengadget.com, press
- Financial Times: interview with Mark Zuckerberg (paywalled; quotes read via Slashdot and Gizmodo)ft.com, press
- Gizmodo: Mark Zuckerberg: Meta Is on the Frontier Nowgizmodo.com, press
- Gizmodo: I Asked Muse to Help Me Book My Holiday Travel. It Didn’t Fly Fargizmodo.com, press
- Reuters via Economic Times: Meta releases Muse Wonder AI models to challenge Anthropic and OpenAIeconomictimes.indiatimes.com, press
- Bloomberg: Meta Says New Muse Model Reaches AI Frontier After Aggressive Push (paywalled, not read)bloomberg.com, press
- Axios: Meta unveils new frontier-class AI models to compete with OpenAI, Anthropic (not read)axios.com, press
Show all 17 sources
- Motley Fool: Why Meta Platforms stock rallied Monday morningfool.com, press
- Cheeky Pint (Substack): Muse Wonder: Zuckerberg and Wang’s $100B AI (video and transcript)cheekypint.substack.com, press
- WinBuzzer: Meta’s new Muse Wonder AI model is closing the gap to Anthropic and OpenAI (Oct 13, 2026)winbuzzer.com, press
- Decrypt: Meta’s new Muse Wonder finally puts Zuckerberg in the frontier AI race (Oct 12, 2026)decrypt.co, press
- The Rundown AI: Meta’s Watermelon ripens into a frontier model (Oct 13, 2026)therundown.ai, press
Reactions
- Artificial Analysis on X: Intelligence Index results for Muse Wonder and Muse Wonder Fullx.com, discussion
- Vals AI on X: Muse Wonder Full debuts at #5 on the Vals Indexx.com, discussion
- Slashdot: Mark Zuckerberg Says Meta Has Reached AI ‘Frontier’, Rejects Calls For Slowdown (FT excerpt)meta.slashdot.org, discussion
- John Collison on X: Cheeky Pint with Zuckerberg and Wang on Muse Wonderx.com, discussion
- Andrew Curran on X: ‘Pacing is out the window’x.com, discussion
- Hacker News discussionnews.ycombinator.com, discussion
- Fireside Alpha on X: Wang on CFO Susan Li’s warning (Cheeky Pint clip and transcript)x.com, discussion
- amit on X: Zuckerberg on the ‘$100B or $200B’ check (quoting a transcript)x.com, discussion
- The Transcript on X: Zuckerberg on Llama 4 and rebuilding the teamx.com, discussion
- Artificial Analysis on X: cost per task and token use of Muse Wonder (thread reply)x.com, discussion
- David Singleton on X: Muse Wonder rolled out first to Muse subscribersx.com, discussion
- BridgeMind on X: ‘Muse Wonder is benchmaxxed’x.com, discussion
Show all 21 sources
- Max Blade on X: Muse Wonder Full vs Opus 5.5, plan limitsx.com, discussion
- Charlie Marsh on X: ‘publishing intelligence without cost is not-great’x.com, discussion
- Alexandr Wang on X: usage-limit bug for Muse Code subscribersx.com, discussion
- Mark Zuckerberg on X: Muse Wonder for subscribersx.com, discussion
- Federico Viticci on X: ‘Muse Wonder feels…great?’x.com, discussion
- Jeff Weinstein (Stripe) on X: working with Meta on agentic commercex.com, discussion
- Supreme Bagholder on X: ‘The subscription sprawl is getting silly’x.com, discussion
- Rob Hallam on X: ‘3 billionaires chatting over beers’ (about 101k views)x.com, discussion
- Paweł Huryn on X: Muse Wonder Full on 105 real bugs (44, vs 45 for GPT-6 Astra)x.com, discussion
Changes
- Added Paweł Huryn’s independent bug-fixing test (found through Hacker News), with a post file
- Artificial Analysis coding-agent breakdown and per-task cost, Vals ProofBench (via WinBuzzer); Decrypt and The Rundown read, no further new facts; Mashable and Bloomberg ‘cutesy agents’ not readable
- Added first-hand reactions’s X list (Viticci’s test, Stripe’s Jeff Weinstein, the subscription-sprawl complaint, Rob Hallam’s quote post), with post files
- Added Alexandr Wang’s post on a usage-limit accounting bug and Zuckerberg’s subscriber post (views via fxtwitter)
- Added the reach on X of the Cheeky Pint passages (the $100-200B check, Susan Li’s warning) and Zuckerberg’s Llama 4 quote as transcribed on X, Artificial Analysis thread details, Singleton on the subscriber rollout, early user criticism and reach figures (X posts via fxtwitter)
- Read the Cheeky Pint transcript (codenames Avocado/Watermelon, team size, costs, the $100–200B bet, next models) and the FT quotes via Slashdot/Gizmodo; price and rate limits confirmed on Meta’s own pricing page; Vals Index scores from vals.ai (correction: Gemini 4 Argon ranks first there, so Wonder Full is not behind Anthropic models only); Gizmodo’s agent test added
Show all 8 changes
- Added the Cheeky Pint Substack page for the Zuckerberg–Wang interview
- Filed (evening)